
Riverflow 2.6 Pro Hires a Judge Before It Shows You the Picture
Sourceful released Riverflow 2.6 Pro on October 29, and the first thing worth saying about it is that it isn't really sold as an image model. It's sold as a workflow with an opinion. The description on its model page reads like a job spec: an integrated reasoning model plans multi-step edits, judges candidates, and only then accepts a result. Reasoning effort is a dial with four positions. Higher settings mean more editing passes and a stricter internal judge.
That's a strange thing to put in front of an image generator, and it's the most interesting thing about it. Most models ask you to describe what you want and then roll dice. This one asks what you want, proposes a path, walks the path, and grades its own work before handing anything back.
The specs, briefly
Riverflow 2.6 Pro is the flagship of a 2.6 family that handles text-to-image and image-to-image in one pipeline. It takes up to 10 input images for editing. It accepts a 33K context. Output sizing is the headline feature: instead of picking a preset, you can pass a literal WIDTHxHEIGHT, up to 16,384 pixels on an edge, 16.8 megapixels total, and an aspect ratio as extreme as 16:1. The 1K/2K/4K presets still exist, and now include 5:4 and 4:5.
Pricing starts at $0.13 per image, and that word "starts" is doing a lot of work. Cost is finalized per job at completion, based on billable processing. Reasoning effort, output size and editing complexity all move the number. A 1280×720 job in the playground shows $0.1501 and 91 seconds. If you're used to thinking in cents per image, this model asks you to think in cents per job, where the job has a variable length.
The three features that reveal who it's for
Most of the spec sheet is table stakes. The interesting parts are the ones that only matter if you're producing commercial imagery at volume.
Custom fonts. You can pass up to two font references through font_inputs, and the model will try to match the lettering, spacing and weight. Anyone who has shipped a campaign knows the failure mode this addresses: the image is beautiful, the headline is in a font that is almost your brand font, and the whole thing is unusable. Matching type is not a creative problem, it's a compliance problem, and treating it as a first-class input is the right call.
Custom scoring. You can supply a scoring_prompt and a scoring_rubric, and the reasoning model will evaluate candidates against your criteria instead of its own. This is the feature I'd expect to be copied first. It means the judge can be told "the logo must be at least 12% of frame width and must not be occluded," and then it actually checks. The gap between "generate something pretty" and "generate something that passes brand review" is where most production budgets die.
Background control. Original, transparent, or a solid color with a hex value. Unglamorous, and the difference between a usable asset and a Photoshop session.
What the judge actually buys you
There's a real argument that self-grading is theater. A model that judges its own output is grading its own homework, and the rubric it invents will flatter the thing it just made. The reason this implementation is more interesting than that critique is that the rubric can be yours, not its.
When you hand it a scoring prompt, you're converting a taste problem into a checklist problem. That's the same move good art direction does: a creative director doesn't say "make it pop," they say "the product needs to read at thumbnail size." Once the criterion is explicit, a model can optimize against it. And unlike a human retoucher, it can do it a hundred times overnight without getting bored.
The cost is latency. The P50 end-to-end time on OpenRouter is about 104 seconds, with a P90 around 171 and a P99 over 327. If you're generating a single hero image, that's fine. If you're generating 200 variants for a test, it's an hour and a half of wall clock, and you'll want to run it in a queue that doesn't care about your feelings.
Availability is the other number to watch: 88.55% over three days, with uptime at 100%. Translation: the endpoint is reachable, but roughly one request in nine didn't return inference. On a model that costs a fifth of a dollar per attempt, that's annoying. On a model you've built a pipeline around, it's a retry policy you need to write before launch.
How it compares
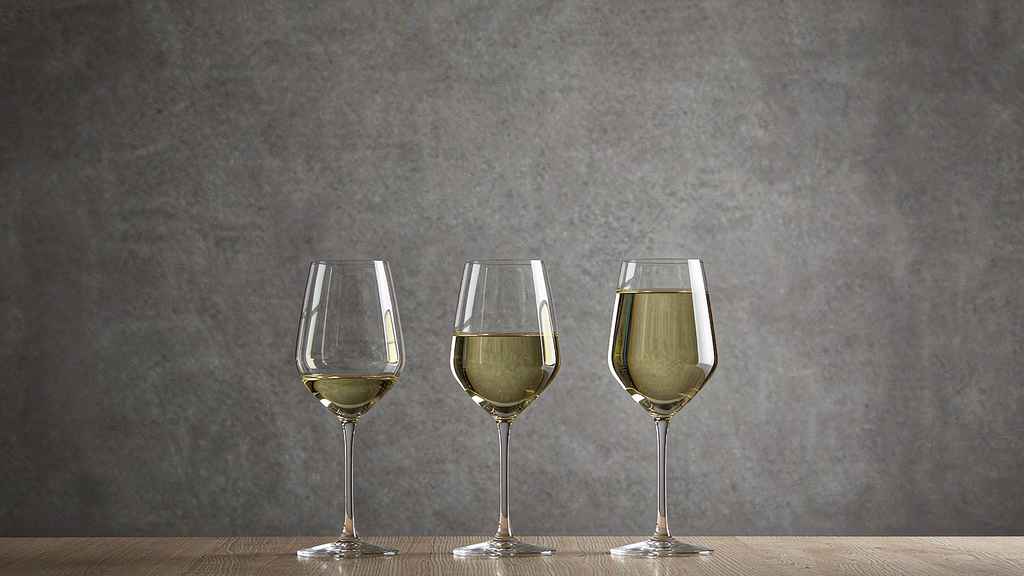
On OpenRouter's shared image benchmark — the "wine glass filled to the brim" prompt, designed to catch models that draw the glass a third full because that's what their training data shows — Riverflow V2.6 Pro passes 3 of 4 checks at $0.157. Nano Banana 2 and 2.1 pass 4 of 4 at $0.06 and $0.035. GPT-5.4 Image 2 passes 4 of 4 at $0.006.
Read that honestly and it hurts a little. On a generic prompt-following test, Riverflow is both more expensive and less accurate than models a tenth its price. That comparison is also unfair, because the wine glass test measures one thing: whether the model obeys an unusual instruction. It says nothing about whether the headline is in the right typeface, whether the transparency is clean, or whether the 16:1 banner actually composes.
Which is the whole argument for a model like this. If your job is "make a picture of a glass," you should use the six-tenths-of-a-cent model and stop reading. If your job is "produce forty on-brand assets that survive legal review," the cost of a bad image isn't the six cents you paid for it. It's the twenty minutes of a designer's time to fix it, times forty.
Should you use it
If you're doing one-off creative exploration, no. The latency and the variable pricing will annoy you, and cheaper models will make prettier pictures more often than you expect.
If you're building an asset pipeline for a brand — packaging, retail, social, anything with a typeface requirement and a background requirement — it's worth an afternoon of testing. Set a scoring rubric that encodes your actual review checklist, run it at medium reasoning, and see whether the judge catches the things your art director catches. That's a much better test than any leaderboard.
The broader point is that image models are splitting into two categories: ones that generate, and ones that produce. Riverflow is firmly in the second, and it's priced like it knows that the difference is measured in retouching hours rather than in cents.
Related articles
The Last Link in the H3 Pipeline Is Now Open Source
A new open-weight refiner takes MiniMax H3 drafts from 768P to 2K locally, in three denoising steps — and it beats the official API on perceptual quality.
Meta Is Testing Its Strangest AI Apps in Southeast Asia First
An AI fitting room in Indonesia, Singapore and Thailand. A pet journal in the Philippines. Neither was announced, and that is the point.
Runware Wants to Build Data Centers the Way Detroit Built Cars
Thirty megawatts a day by 2028, pods online within 48 hours, a gigawatt a month. The constraint on AI capacity stopped being chips and became the two years it takes to build a building.
Ollie Had SOC 2 and $7.5 Million. It Still Couldn't Outship Muse.
A privacy-first family assistant with a Khosla-led seed round and a real SOC 2 audit is closing on November 6. The lesson is not about privacy. It is about distribution.