
NVIDIA's $4,999 DGX Spark 64GB Puts a Petaflop on the Desk for Always-On Agents
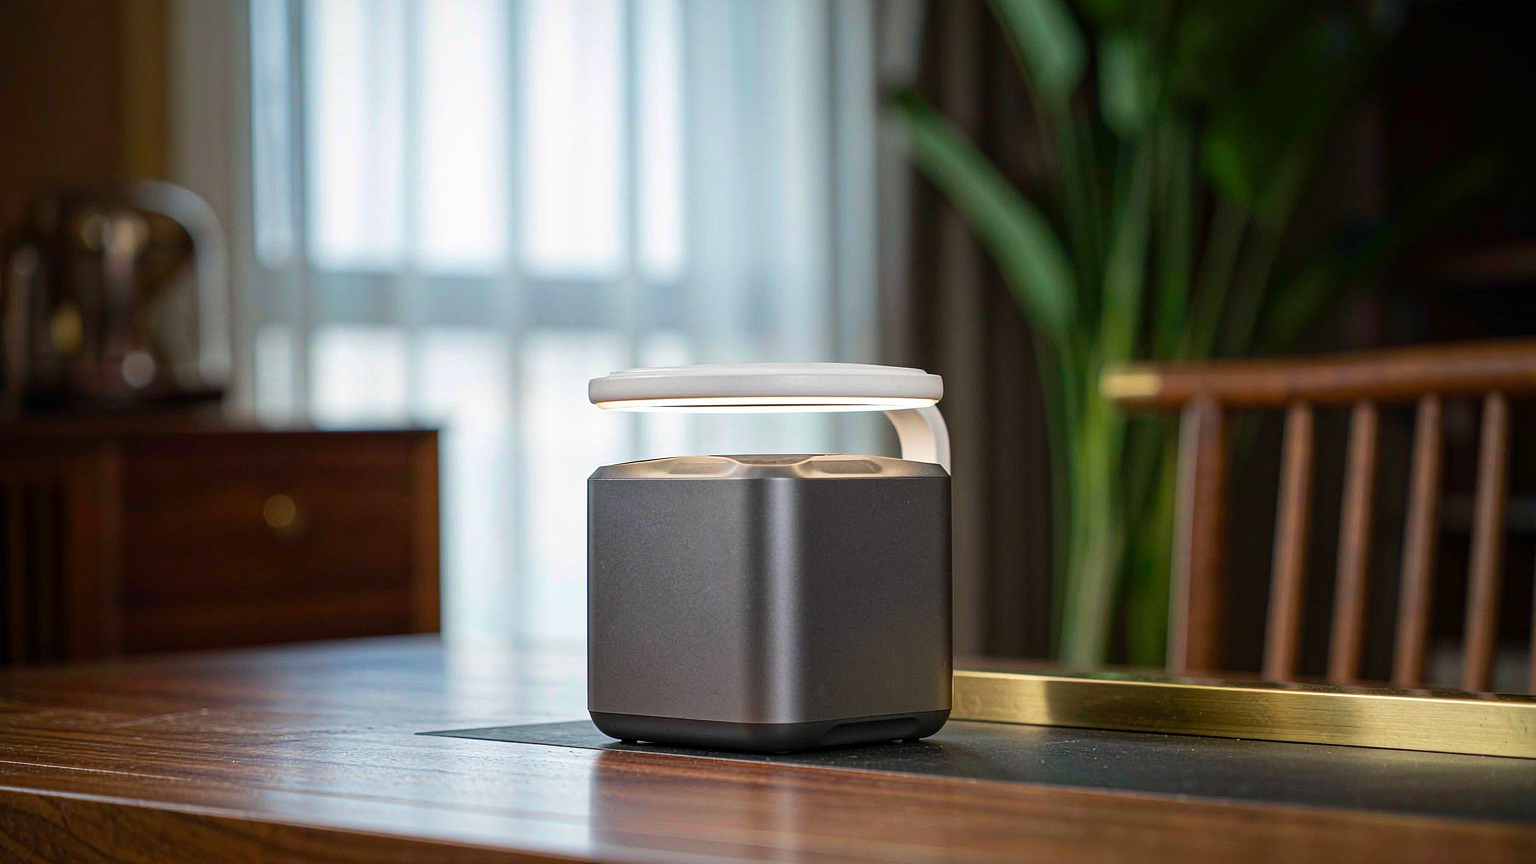
NVIDIA has confirmed a 64GB version of its DGX Spark desktop AI computer, priced from $4,999 and shipping October 23 through Acer, Asus, Dell, Gigabyte, HP, MSI and H3C. The 128GB model stays on sale at $6,950. Both are built on the GB10 Grace Blackwell superchip, which pairs a Blackwell GPU with a 20-core Arm CPU on one package and shares a single pool of LPDDR5X memory between them.
The architecture is the selling point. Coherent unified memory means the CPU and GPU see the same address space, so you stop copying data between system RAM and VRAM. On a 64GB box, roughly 8GB goes to the operating system, leaving about 56GB for model weights and the KV cache that grows with context length. NVIDIA rates the chip at up to one petaflop of AI compute in the FP4 format.
What 64GB actually runs
NVIDIA positions the 64GB configuration for models in the 30B to 35B class: Qwen3.8-27B, Gemma 4 26B, Meta Muse Glimmer and Nemotron 3.5 Lightning. With NVFP4 quantization, which NVIDIA says keeps accuracy, one box can handle models up to roughly 100B parameters. That is the whole point of the machine. A year ago, models at that level needed a server rack. Now they fit in a box the size of a large lunch.
The tradeoff is memory bandwidth. At 273GB/s, the Spark is not built to serve a chat product to a hundred concurrent users. It is built for long inputs and short outputs: reading a repository, a log dump or a stack of documents and writing a short result. That shape fits agents well, because an agent spends most of its time reading context and only occasionally produces an answer.
The lineage behind the box
The Spark is not NVIDIA's first attempt at putting serious compute under a desk. The 128GB version already existed at a higher price, and the 64GB model is a deliberate move downmarket. Keeping the same GB10 chip and the same unified memory design while cutting memory in half lowers the entry cost without changing what the machine is for. That matters because the earlier model was priced as a workstation, and a workstation price limits who can buy one.
There is a second reason the 64GB configuration makes sense now rather than a year ago. The open models that fit in 56GB are good enough to be worth running. A 27B model with quantized weights and a long context window can handle real coding and research tasks rather than toy prompts. Six months ago, running the equivalent capability locally meant a bigger box and a bigger bill. The hardware and the models arrived at the same threshold, and that is what makes the price cut meaningful rather than decorative.
Clustering is a first-class feature
Every DGX Spark ships with a ConnectX-7 network card running at up to 200GbE, and the free NVIDIA Sync app handles setup. Its Cluster Assistant configures the networking so you can join up to four units without being a network administrator. Two 64GB Sparks pool to 128GB, and NVIDIA says that pair delivers up to 1.7 times the performance of a single 128GB model, because the combined compute and bandwidth are roughly doubled. A direct cable connects a pair; four units need a switch.
The practical effect is a sliding scale. Start with one box for experimenting, add a second for a real workload, and keep going until the workload outgrows local hardware. Time to first token improves most when you scale, which is what matters for agents that read long inputs before acting.
The software layer is where the agent story lives
The Spark ships with DGX OS, the CUDA stack, and the usual tooling: PyTorch, Jupyter, Ollama, plus tuned support for vLLM and llama.cpp. NVIDIA claims up to 1.9 times faster local agent inference with its optimizations. It also bundles OpenShell, part of the NVIDIA Agent Toolkit, which sets policy-based boundaries on what an agent can do.
That last piece connects to a broader trend. As agents move from demo to daily use, the bottleneck stops being the model and becomes reliability. A local machine that runs an agent overnight needs to make tool calls correctly, recover from failures and not wander outside its scope. NVIDIA is leaning on exactly this: the Spark is aimed at always-on agents, not one-off prompts.
Perplexity has already adapted to the hardware, shipping an optimized portable computer agent that can run a 118B model locally on the device. That is a notable signal, because Perplexity is a cloud-first company. If it is building for local hardware, it expects a market of users who want the model on their own machine.
Who this is for, and who it is not
The $4,999 price puts the Spark in professional territory, not consumer. The people who benefit are researchers, independent developers and small teams who run agents often enough that per-token API fees add up, or who work with data that cannot leave their own hardware. Fine-tuning a coding model on a private repository, running a day-one evaluation on a new open model, or keeping several models resident at once are all jobs that fit the unified memory design.
For everyone else, the calculus is less clear. If you use AI a few times a day, cloud APIs are cheaper and simpler. The Spark makes sense when your usage is high, your data is sensitive, or your workload runs continuously. The 64GB model lowers the entry price but does not change that logic.
One detail is worth flagging for anyone budgeting. The 56GB of usable memory has to cover the weights and the KV cache together. Long context eats cache, and agent workloads are long by nature. A quantized model that technically fits can still hit the wall once the context grows, which is why NVIDIA points at the 17GB quantized build of a larger model as the practical choice over its 55GB full-precision version. Fitting a model and running it well on a long task are two different tests.
The bigger signal
The interesting part of this release is not the price cut. It is that a 27B or 30B model running on a desktop is now close enough to frontier behavior from a few months ago that the machine is worth building a product around. The hardware and the open models have converged at the same spot: a box under a desk, running an agent that works while you sleep, with the data never leaving the building.
NVIDIA is betting that enough developers want that to justify a product line. The list of OEMs shipping the Spark suggests it thinks the answer is yes, and that the next few years of AI work will not all happen in a data center.
Related articles
A Wheeled Semi-Humanoid Finished an Hour of Laundry Without Help
Individual tasks can succeed while a workflow still fails. Dyna changed the metric.
LTX 2.5 Wants to Render Your Blocky Blender Draft Into a Finished Shot
You do not control what happens in text-to-video. This tries to fix that.
ServiceNow Turns Agent Failures Into Training Data
Generation without verification is noise. The gates are the product.
One Framework for Language and Vision: Horizon's 1.6B Open Model
A bet that the bridges between language and vision were never needed.