
The Sub-Agent Economy: Why Cheap Models Are the Real Agent Story
The most consequential AI release in early October was the cheapest one. On October 7, Anthropic shipped Claude Haiku 5.5 and said its average running cost was about 75 percent lower than the previous Haiku. For requests under 100,000 tokens, the API price dropped roughly 90 percent, to ten cents per million input tokens and fifty cents per million output. Anthropic also cut the cache-read price on Sonnet 5.5 in half.
Cheap models are easy to dismiss. They look like a pricing move, not a capability story. But the interesting detail in this release is not the price. It is what Haiku 5.5 is for.
The small model grew up
The old knock on small models was that they were fine for simple tasks and useless for real ones. That gap has narrowed fast. On the Terminal-Bench coding evaluation, Haiku 4.5 scored zero. Haiku 5.5 scored 39.2 percent. On OSWorld, which tests operating a computer through its interface, it went from 15.7 percent to 72.4 percent, ahead of the comparable GPT-6 Luna at 48.9 percent.
Anthropic also gave Haiku the first adjustable reasoning effort in the line, with five levels from low to max. That lets a developer spend compute where it helps and skip it where it does not, which is a small feature with a large effect on the cost of running something continuously.
The sub-agent framing
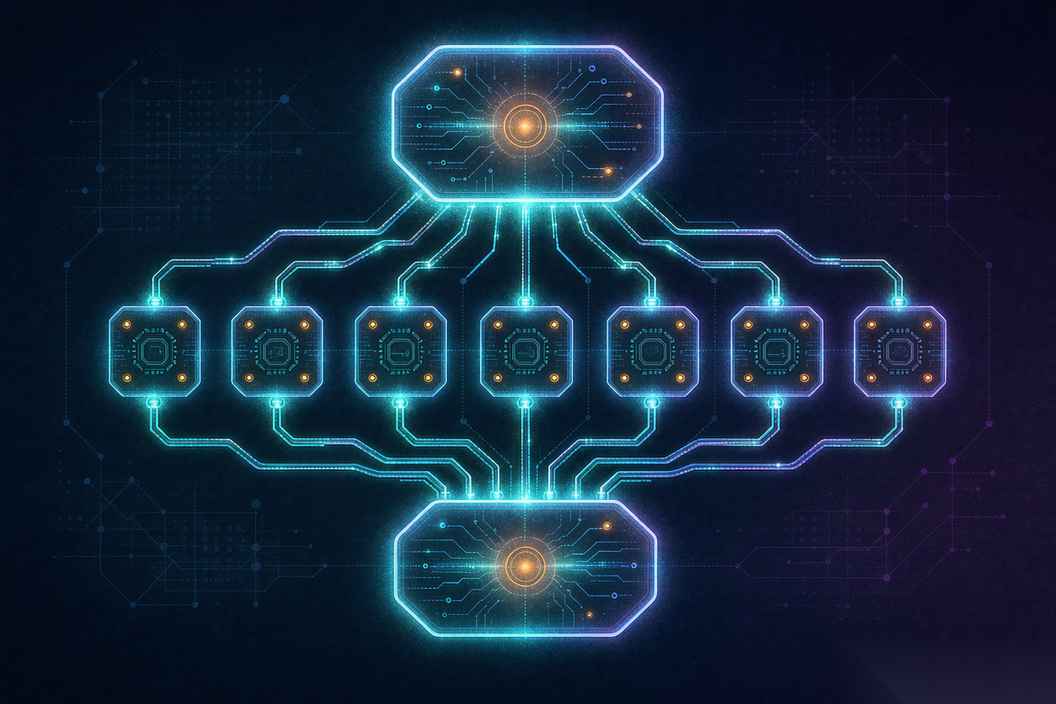
The part of the release worth underlining is positioning. Anthropic said Haiku 5.5 can serve as a sub-agent for the larger Opus 5.5 and Sonnet 5.5. In plain terms, a flagship model plans and decides, and Haiku does the doing: organizing documents, operating a computer, handling data.
That is a real architectural shift, and it reframes the cost conversation. It is not only that each call is cheaper. It is that one expensive planning call can now fan out into many cheap execution calls. An agent that used to run one flagship model for every step can run a flagship for the hard part and Haiku for everything else. The bill can fall by more than the per-token discount suggests, because you are changing how many expensive calls happen at all.
Anthropic's rivals are converging on the same shape from other angles. Google's Gemini 4 Argon, launched October 1, is aimed at coding, research, finance and legal work, and it supports output up to a million tokens for large reviews. OpenAI's mid-tier models have been cutting prices to hold ground. The launch messaging differs, but the underlying bet is shared: the work is not one model answering one question. It is many calls, orchestrated, and the orchestrator needs cheap hands.
Why the bottleneck moved
There is a number that explains the urgency. Analysts tracking the field put global daily active agents at roughly 79 million in 2026, up from about 29 million the year before, with projections into the billions by 2030. Whatever the exact figure, the direction is clear. Agents are moving from demonstrations to production, and the thing that stops a production agent is rarely that the model is too dumb. It is that running it enough times costs too much.
That is why the industry has started to talk about the orchestration layer, the piece that breaks a request into steps, routes each step to an appropriate model, and assembles the result. When the base models get cheaper, that layer becomes more valuable, not less, because it is what decides where the cheap model goes.
How a chain actually splits the work
Abstract talk about sub-agents gets clearer with a concrete job. Suppose you ask an agent to research a market and produce a briefing. The flagship model reads the request, decides what to look for, and plans the steps. A small model then does the grind: it visits pages, extracts numbers, reformats tables, deduplicates sources, and checks that each claim has a citation. The flagship comes back at the end to write the synthesis and decide whether the draft is good enough. One expensive call at each end, many cheap calls in the middle.
That pattern repeats across tasks. Anything that is high volume and low ambiguity is a candidate for the cheap model: filling forms, reading logs, classifying support tickets, checking that a document matches a template. Anything that requires judgment about what to do next stays with the flagship. The line is not fixed, and the interesting engineering work right now is deciding where it sits for each workflow.
Anthropic's adjustable reasoning effort fits neatly here. A task that needs a light touch can run at low effort, and one that needs more care can be dialed up without switching models. In practice that means the same cheap model can serve both a quick classification and a careful review, which reduces how many moving parts a team has to manage.
What the price cut changes about products
Cheaper execution changes which products are worth building. A feature that runs an agent on every incoming message made no sense when each run cost real money. It makes sense when the run costs a fraction of a cent. The result is a wave of features that were technically possible for a year and economically impossible until now: always-on monitors, per-item enrichment, background reviewers that check every artifact instead of a sample.
There is a trap in that, and it is easy to fall into. When execution is cheap, teams stop measuring it. A workflow that runs a thousand cheap calls a day looks harmless on a per-call basis and can still add up to a surprising monthly bill once retries, failures and escalation to an expensive model are included. The number that matters is the cost of a completed task, not the cost of a single call.
The benchmark problem with small models
Small models are getting better on benchmarks, and benchmarks are exactly where the improvement is easiest to overread. A headline score on an operating-computer test says the model can follow a known sequence of interface steps. It says much less about whether the model knows when to stop, when to ask for help, or when a task has quietly gone wrong. Those behaviors are where cheap agents fail in production, and they are hard to score.
The practical defense is unglamorous. Give a cheap sub-agent a narrow job, a clear definition of done, and a way to escalate rather than guess. Then watch what it does on the edge cases for a week before trusting it with anything that matters. A cheap model that knows the limits of its task is more useful than a clever one that improvises.
The honest caveats
A cheap model that is confident and wrong is worse than an expensive one, and agent chains multiply that risk. Every additional step is a place for an error to enter and propagate. Price per token says nothing about whether the cheap model handled an ambiguous instruction the way a person would.
There is also a governance gap that has not been closed. Guidance from NIST and CISA in late September treats agents as low-trust non-human identities and calls for short-lived credentials, maintained inventories and human approval for higher-risk actions. Most organizations have neither the inventories nor the approval flows. Cheap execution makes it easier to run many agents and harder to know how many are running.
What this means if you build
The useful habit to build now is to stop reaching for the biggest model by default. Map a task into planning and execution, spend the flagship where judgment is required, and route the rest to a small model. Measure the whole chain, not a single call.
Haiku 5.5 is not the story because it is cheap. It is the story because the cheap tier finally got good enough to carry the parts of an agent that used to need the expensive one.
Related articles
AI Short Drama Hit the Hot Search, and Live-Action Shoots Fell 70%
Only one of the top 20 titles on a major Chinese drama chart was made with real actors. AI costs about a tenth as much to produce, and it is rewriting the whole pipeline.
Decagon's PACT Protocol Wants Consent to Be a Standard
Decagon open-sourced a protocol for verifying a personal agent's identity and the permissions a customer granted it. It is plumbing, and it decides whether the agent economy works.
The AI Reunion Wave China Can't Decide How to Feel About
AI tribute films brought departed public figures back to Chinese screens and pulled in hundreds of thousands of likes. Then the backlash arrived, and it was about consent.
Apple Published an Open Multimodal Model and Barely Told Anyone
Apple's research-first release slipped past the mainstream, but the model's fine-grained visual grounding says a lot about where its AI stack is heading.