
Ten Reference Images at Once: AI Image Editing Moves from Single Shots to Composites
For a long time, AI image editing meant one reference image and one instruction. Show the model a photo, tell it what to change, get a result. That covered a lot, but it missed the way people actually think about images, which is often in terms of combining several sources into one.
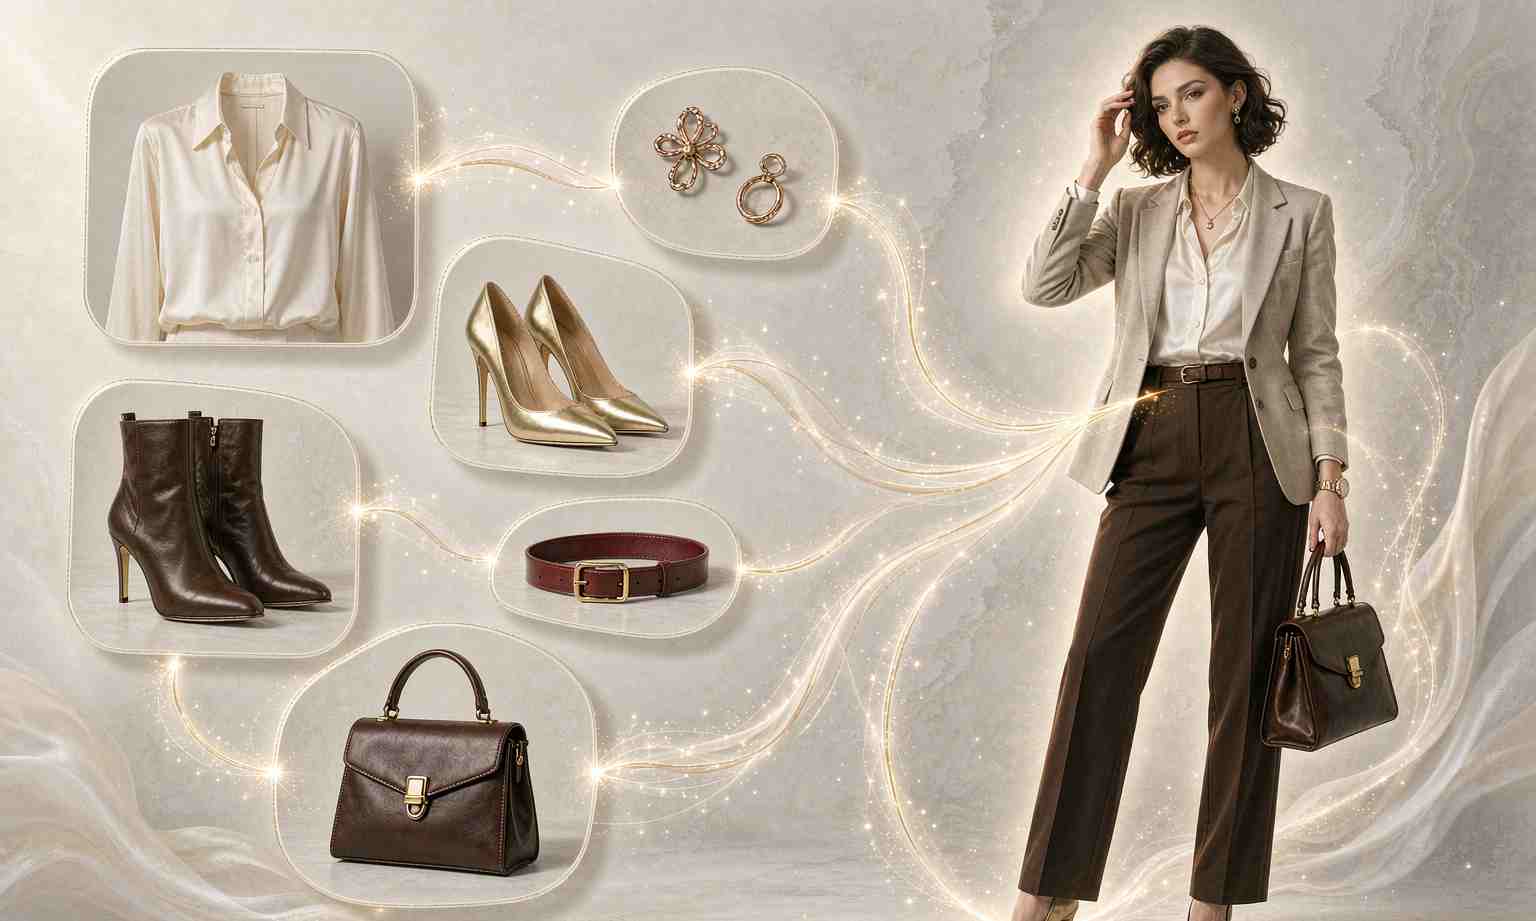
Qwen-Image 2.1 pushes the reference count up to ten. The model can take six separate portraits and merge them into a single group photo, or assemble a full outfit from a model, a shirt, shoes, a bag, and a hat, one reference each. That is a different kind of task than single-image editing, and it is the kind of task that shows up constantly in real work.
Think about the practical cases. A brand wants a campaign image with three of its products arranged in a scene, each product provided as a separate photo. A wedding photographer wants to combine several shots into one. A fashion seller wants to show a complete look built from catalog pieces. A character designer wants to keep a face consistent across a dozen variations. Single-reference editing forces you to regenerate and patch, feeding one image at a time and hoping the model keeps everything else consistent. Multi-reference editing lets you feed the model the parts and let it compose.
The hard part has always been computational. More reference images means more tokens, and more tokens usually means slower generation and more memory. If you naively feed ten references into a model and re-encode them at every step of the diffusion process, the cost explodes, and the feature becomes unusable on anything but a datacenter GPU. Qwen's approach to this is a mixed-granularity attention scheme. Text instructions get a token-level causal mask, while image generation gets a chunk-level mask. A KV cache reuse scheme lets the reference images and instructions be computed once and reused as static context across steps, instead of recomputing them every step.
The idea is simple enough. If the references do not change during generation, there is no reason to re-encode them at every step. Compute them once, cache them, and spend the compute on the parts that actually change. That is the kind of engineering that does not make headlines but determines whether a feature is actually usable on consumer hardware. The difference between "supports ten references" on a spec sheet and "supports ten references without timing out" in practice is exactly this kind of caching.
The jump from two references to ten is more than a bigger number. It changes what you can describe. Single-image editing produces variations, the same picture altered. Multi-image editing produces combinations, new pictures assembled from parts, and combinations are where a lot of commercial value lives. Product photography, group portraits, lookbooks, scene composition, storyboarding from a set of assets, all of it opens up when the model can hold several inputs at once and reason about how they fit together.
This also signals a broader direction for image models. The early models were text-to-image: describe a scene, get a picture. Then came image-to-image editing: give it a picture, describe a change. Now the frontier is composition, feeding a model many inputs and letting it reason about how they combine. That is closer to how a human designer works, assembling from pieces rather than describing from scratch, and it points toward models that behave less like generators and more like collaborators.
There is a privacy and control angle worth noting. When a model can compose from ten references, the user keeps control of the inputs. Instead of describing a product and hoping the model renders it accurately, you feed it the actual product photo. Instead of describing a person, you feed their real image, within whatever consent boundaries apply. Multi-reference editing is, in a sense, a step toward grounded generation, where the model is anchored to real assets rather than hallucinating from a text description.
There are real limits still. Identity preservation across multiple people in one image remains finicky, and the more references you feed, the more chances for the model to confuse attributes between them, the wrong face on the wrong body, the wrong color on the wrong object. The ten-image ceiling is a step, not a solved problem, and the failure modes get weirder as the input count grows. The team has clearly done the engineering work to make it fast, but the quality work is ongoing.
The local edit controls are part of the same package. You can draw circles, paint annotations, or pass a separate mask image to target an edit to one region without touching the rest. Combined with multi-reference input, this starts to look like a real compositing tool, the kind of thing that used to require layers in a graphics editor, now expressible as a set of references and instructions to a single model.
For anyone building creative tools, the lesson is straightforward. The next wave of differentiation is not "better single images." It is "how many things can the model hold and combine at once, and how precisely can you tell it what to change." Ten references is the current answer. It will not stay ten for long.
There is a broader frame worth putting around this. For years, the promise of AI image generation was "describe it, get it." That promise worked for casual use, but it never quite worked for professionals, because professionals rarely start from a blank description. They start from assets, a product photo, a reference image, a brand guideline, a face that has to stay consistent. The move toward multi-reference editing is, at its core, a concession to that reality. The model is being taught to start from what the user already has, rather than from what the user can describe.
That is why the engineering matters. Holding ten references in context and keeping them distinct is not just a bigger version of holding one. It is a different problem, the difference between remembering a single face and remembering ten people well enough to tell them apart in a group photo. The chunk-level masking and KV cache reuse that Qwen describes are the specific techniques for solving that problem, and they are the kind of detail that determines whether the feature works in practice or only in a demo.
The commercial implication is direct. The workflows that multi-reference editing unlocks, product compositing, group portraiture, lookbooks, brand asset generation, are all things people currently pay for, either in tools or in labor. If a model can do them well enough, the value shifts from the human labor of compositing to the model's ability to hold and combine. That is a real economic shift, and it is why this feature, more than the benchmark-friendly ones, is the one to watch for where the industry is actually heading.
There is also a creative angle that is easy to miss. Multi-reference editing changes what counts as "prompting." A user who feeds ten references is not writing a description, they are curating a set, making choices about what to include and what to leave out. That is closer to art direction than to prompt engineering, and it points toward a future where the creative act in AI image work is as much about selection and combination as it is about language. The ten-reference ceiling is, in that sense, the first real step toward image models that treat the user as a director rather than a requester.
Related articles
Training Text-to-Image Models Just Got 3.6 Times Faster
The efficiency frontier is moving as fast as the capability frontier. A 3.6x training speedup is the kind of progress that shows up later as a model you can actually run.
Native Transparency Is Quietly the Most Useful New Feature in AI Images
Everyone asks for realism. Designers ask for a transparent background. Why native alpha-channel generation is the quiet feature that changes real workflows.
Alibaba's Qwen-Image 2.1 Just Changed the Open Model Licensing Conversation
The technical specs are impressive, but the license is the real story. Qwen-Image 2.1 drops Apache 2.0 for a research license, and the fine print now matters more than ever.
Tongyi Wanxiang Qwen-Image 2.1 Goes Open Source: How a 7B Small Model Fits Transparent Images and 10-Image Editing on a Single Consumer GPU
A 7B open-source image generation model — how does it squeeze transparent images and multi-image editing onto a 6GB GPU? Breaking down Qwen-Image 2.1's core upgrades and its licensing shift.